Zero Trust and Video Calls: What to Expect
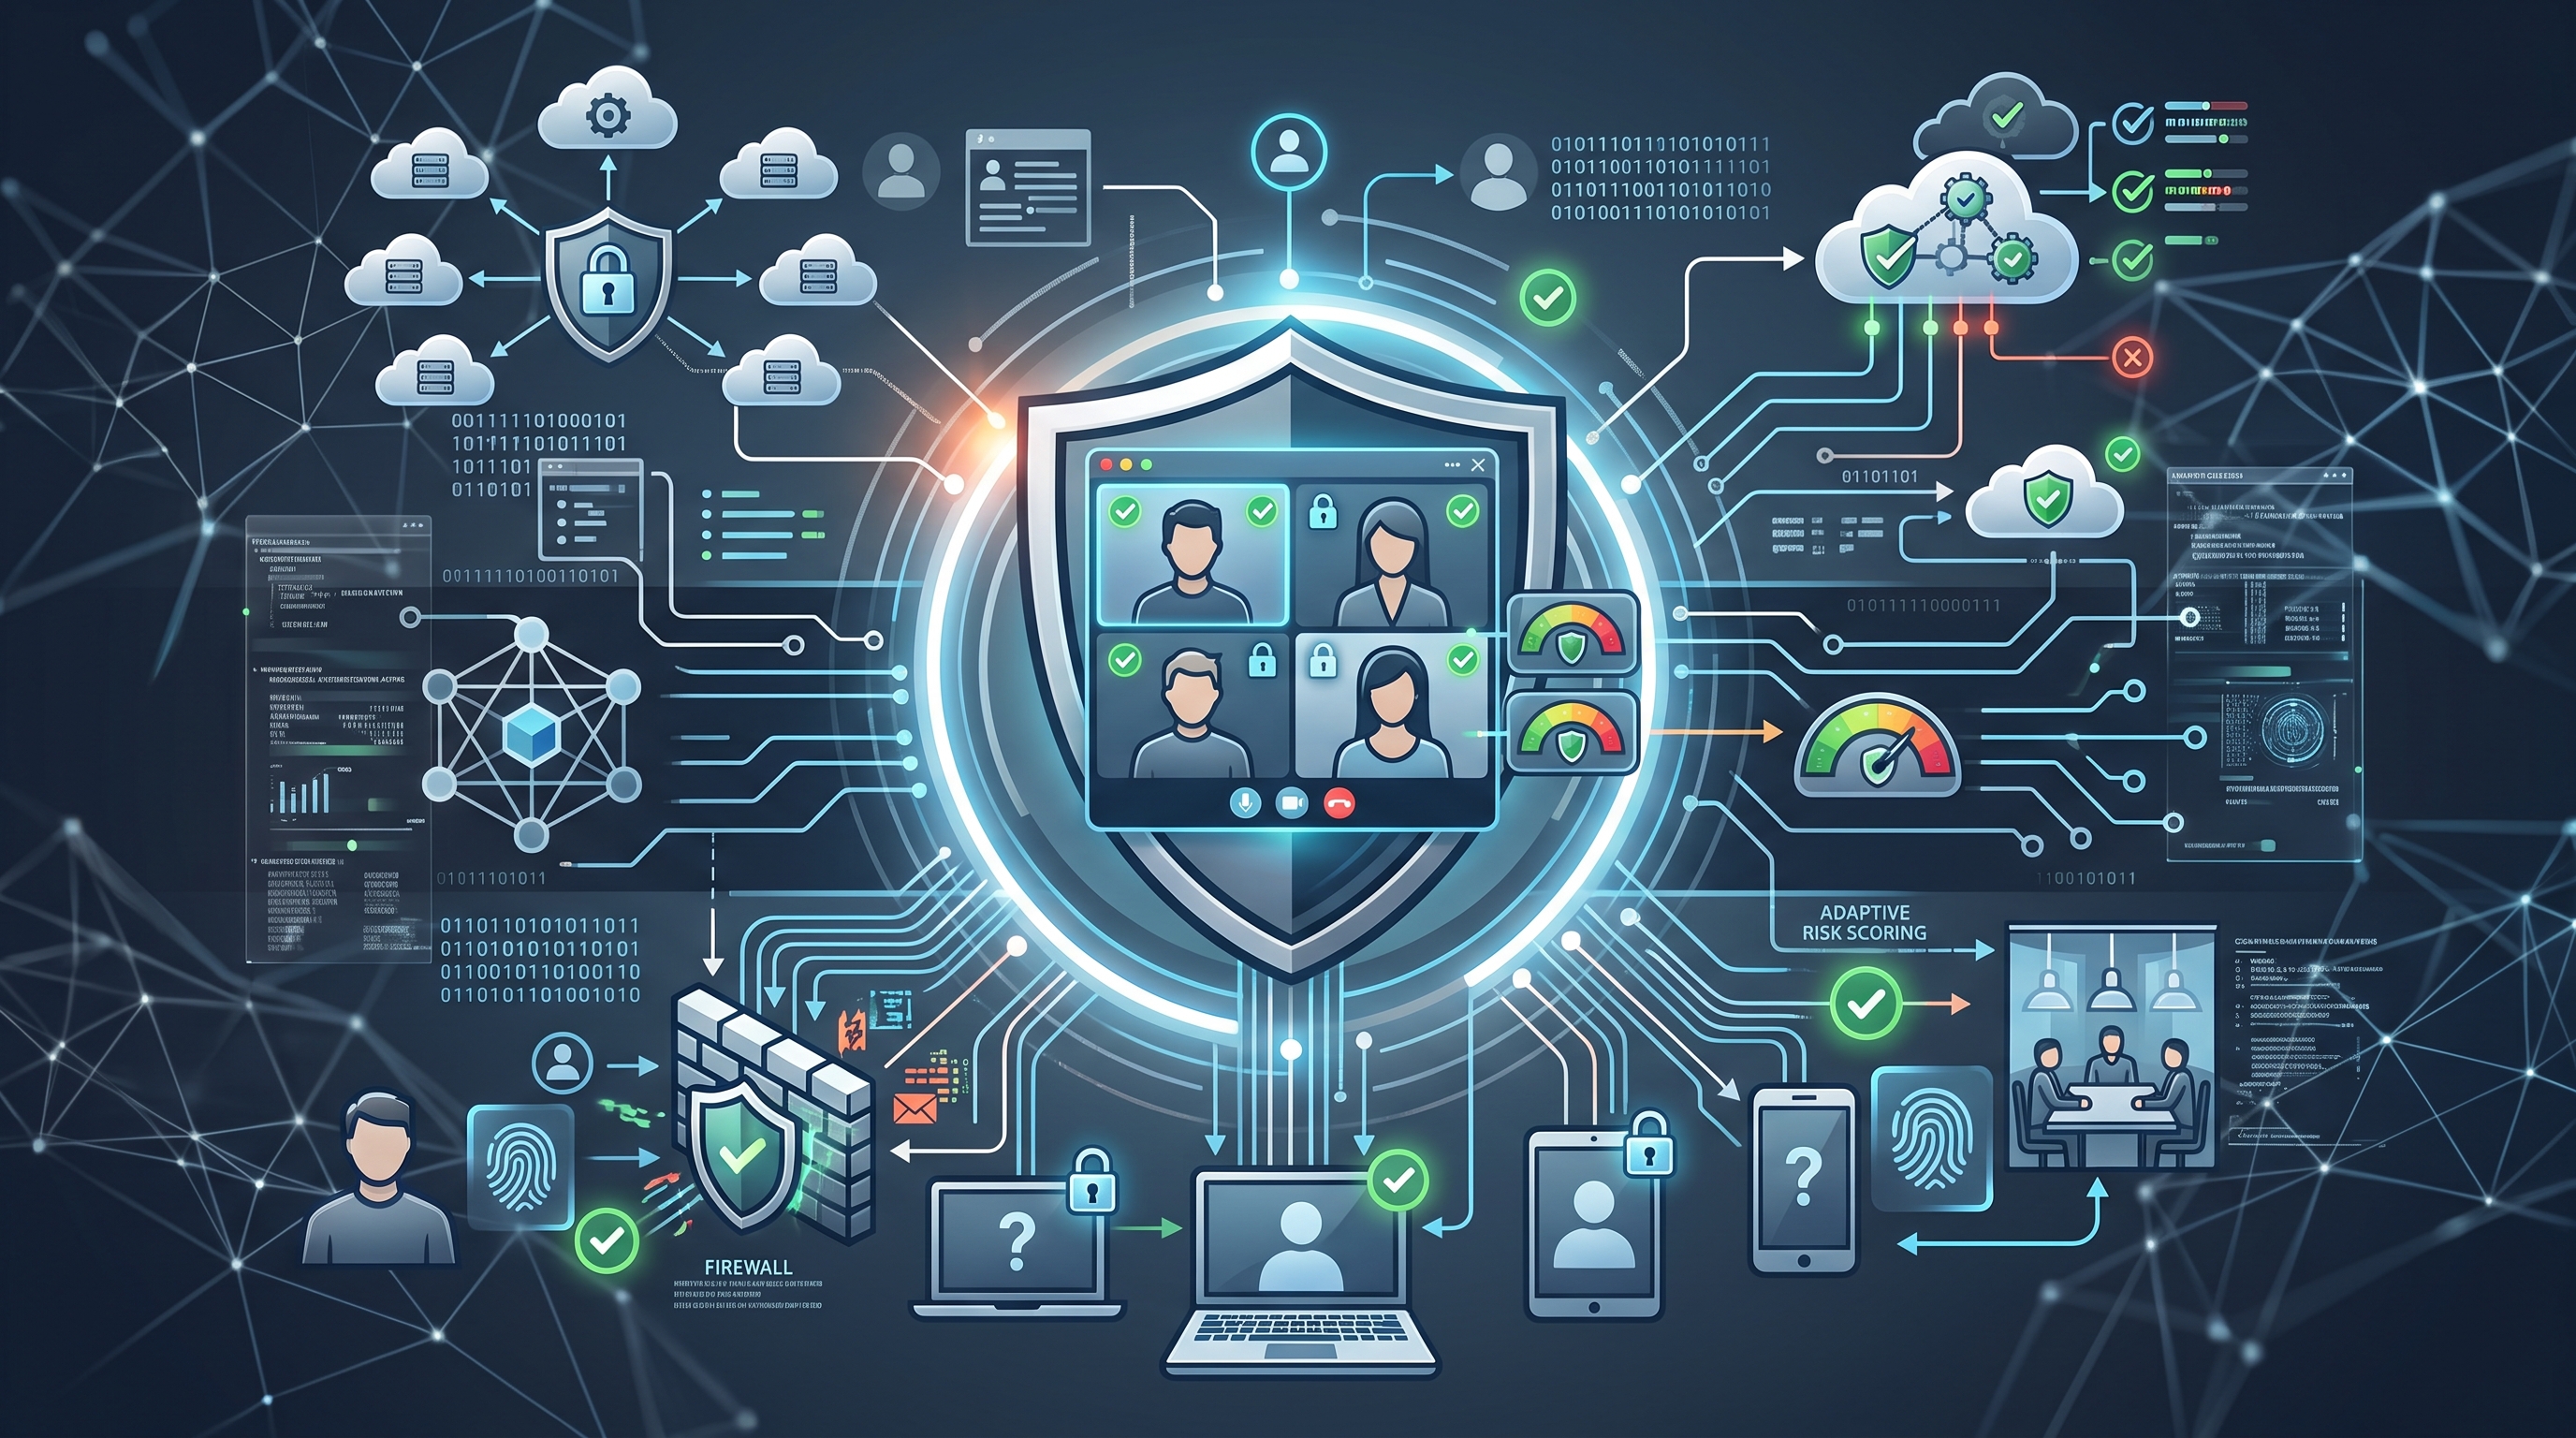
Zero Trust isn't a new idea anymore, and it isn't optional in a lot of places either. NIST formalized it in Special Publication 800-207 back in August 2020. The following year, US Executive Order 14028 directed federal agencies to adopt it as a foundational architecture, and by January 2022, OMB Memorandum M-22-09 turned that into a hard deadline: full Zero Trust implementation across federal agencies by the end of fiscal year 2024. This is settled architecture doctrine at this point, not an emerging trend, and not just a US story either — which makes it worth asking what it actually means once it reaches real-time video communications specifically.
Zero Trust in one sentence
Stop trusting a request because of where it came from, and start verifying it on its own terms, every time. NIST's own model spells this out as a handful of concrete principles: access is granted per session, not per network; every asset's identity and security posture gets checked continuously, not just at login; and policy decisions weigh identity, device health, and behavior together, dynamically, rather than relying on a fixed perimeter.
What that actually means for a video call
A few of these principles map onto video communications more directly than you might expect:
- Per-session access is already familiar territory. A short-lived token that grants access to one specific call, rather than a standing account with broad access, is exactly the model most WebRTC platforms already use for joining a session. Zero Trust doesn't introduce this idea to video calls; it validates an approach the field had already converged on.
- Encryption by default is a real head start — with a caveat. WebRTC secures every hop with DTLS-SRTP as a baseline requirement, not an optional add-on; legacy telephony and video systems had to bolt encryption on after the fact. But "every hop" isn't the same as end-to-end: in a typical multi-party call, the media server (the SFU) sits between participants precisely so it can decrypt, inspect, and route — which makes it a trusted party by default, not a blind courier. A strict reading of Zero Trust has to reckon with that.
- Device and identity posture become part of joining a call, not just logging into an app. A Zero Trust model doesn't stop at "is this the right person"; it asks whether the device they're joining from meets the organization's own security requirements before granting access, the same way it would for any other resource.
- Verification doesn't stop once the call starts. Continuous monitoring is one of NIST's core tenets, not a one-time check at the door. For a video call, that means the platform keeps evaluating the session for as long as it runs, not just at the moment someone joins.
Taking encryption further: keeping the media server out too
If nothing on the network path should be trusted implicitly, that has to include the media server itself, not just the network between it and the participants. Standard SFU-based WebRTC doesn't do this: DTLS-SRTP is negotiated separately between each participant and the server, so the server holds keys and can see plaintext media by design; that's how it does the work of forwarding, adapting, and routing streams.
Getting the media server out of that trust boundary takes two things: a way to encrypt media frames with a key the server never has, and a way for participants to agree on that key as a group in the first place.
- Frame-level encryption. Browsers expose a hook for this through the WebRTC Encoded Transform API, commonly known as Insertable Streams: a point in the pipeline, after encoding and before packetization, where an application can add its own encryption layer. SFrame (RFC 9605, August 2024) standardizes exactly this: each frame is encrypted before it's wrapped in RTP/SRTP, with a key the SFU never sees. The SFU still reads the SRTP headers it needs for routing and congestion control; it just can't decrypt the payload anymore.
- Group key agreement. Encrypting frames only helps if every participant can get the
right key, efficiently, as people join and leave a call. That's what
MLS (Messaging Layer Security, RFC 9420, July
- is built for: a standardized protocol for a group to agree on and rotate a shared key without the cost growing linearly with group size. It's already running in production for exactly this purpose: Cisco Webex uses MLS for end-to-end encrypted conference calls, and Discord uses it for E2EE voice and video.
Put those two together and the SFU genuinely becomes what NIST's model asks for: infrastructure that moves packets without being implicitly trusted with their contents. And because MLS was designed for messaging in the first place, the same group key it manages can secure a call's chat alongside its media — one key-agreement layer, not two bolted on independently.
This is where Zero Trust and video specifically get interesting: the network-level story (per-session access, device posture, continuous verification) is largely solved territory already. The media-server-as-trusted-party problem is the part still actively being worked out.
The EU side: NIS2 and data protection
The US federal mandate isn't the only regulatory pressure pushing toward this model. The EU doesn't have a single "adopt Zero Trust" order the way OMB M-22-09 is for US federal agencies, but the NIS2 Directive — which EU member states had to transpose into national law by October 17, 2024 — requires exactly the category of continuous, risk-based security measures Zero Trust is built around: ongoing risk assessment, access control, and incident detection, not a one-time perimeter check.
Zero Trust also runs into a genuine tension with EU data protection law that's worth naming honestly, not glossing over. One of NIST's own tenets calls for collecting as much information as possible about the state of assets and communications, to continuously improve security posture. GDPR's data-minimisation principle (Article 5(1)(c)) pulls the opposite way by default: personal data has to be "adequate, relevant and limited to what is necessary" for its purpose. Continuous monitoring and logging — the same mechanism that makes Zero Trust's per-session verification and audit trail meaningful in the first place — has to be scoped deliberately: proportionate to a real security purpose, not maximalist by default just because more data feels safer.
One practical way to square that circle: pseudonymize the audit trail itself. GDPR defines pseudonymisation (Article 4(5)) as processing data so it can no longer be attributed to a specific person without separate, additionally-protected information — and it's worth being precise about what that does and doesn't do. Pseudonymized data is still personal data under GDPR if re-identification is reasonably possible by anyone (Recital 26); pseudonymization doesn't take an audit trail out of GDPR's scope. What it changes is who can actually perform that re-identification.
In practice, that means the audit trail a media server keeps — who joined, when, from where — can reference participants by an opaque, untraceable ID instead of a real identity, with the mapping between that ID and the actual person generated and held client-side, encrypted with a key the service provider never has. The server ends up with a complete, continuously logged audit trail — exactly what Zero Trust's monitoring tenet asks for — without ever holding the information needed to identify anyone in it. The data controller (the organization running the call, not the infrastructure provider) keeps sole control over when, or whether, an entry actually gets re-linked to a real identity. That's the shape that lets Zero Trust's logging instinct and GDPR's minimization principle coexist instead of fighting each other: the visibility a security team needs and the identifiability GDPR restricts turn out to be separable.
What this means for recording and auditing
That last point connects directly to something we've written about before: why silent observation in a call center demands more auditing, not less. Zero Trust's own principle — continuously monitor and log the state of every session — is the same argument, just arriving from the security-architecture side instead of the compliance side. Once an organization is expected to log and evaluate activity continuously as a matter of policy, a video platform that treats logging as an afterthought stops being a viable option.
What to expect going forward
Neither the US federal deadline nor NIS2 applies directly to every organization, but requirements like these tend to flow downstream anyway, through vendor and supply-chain obligations, to contractors and regulated industries well beyond who's technically in scope, and plenty of private-sector security teams have adopted the same model independently. The practical effect for video communications: platforms will increasingly be expected to plug into an organization's existing identity provider and device-posture tooling, rather than operate as their own separate trust silo with its own login and its own rules. For anyone building or evaluating real-time video infrastructure, that's the shift worth planning around — not whether Zero Trust arrives, but how a video platform fits into it once it does.